Local AI Benchmarks Comparing LLM Performance Tiers
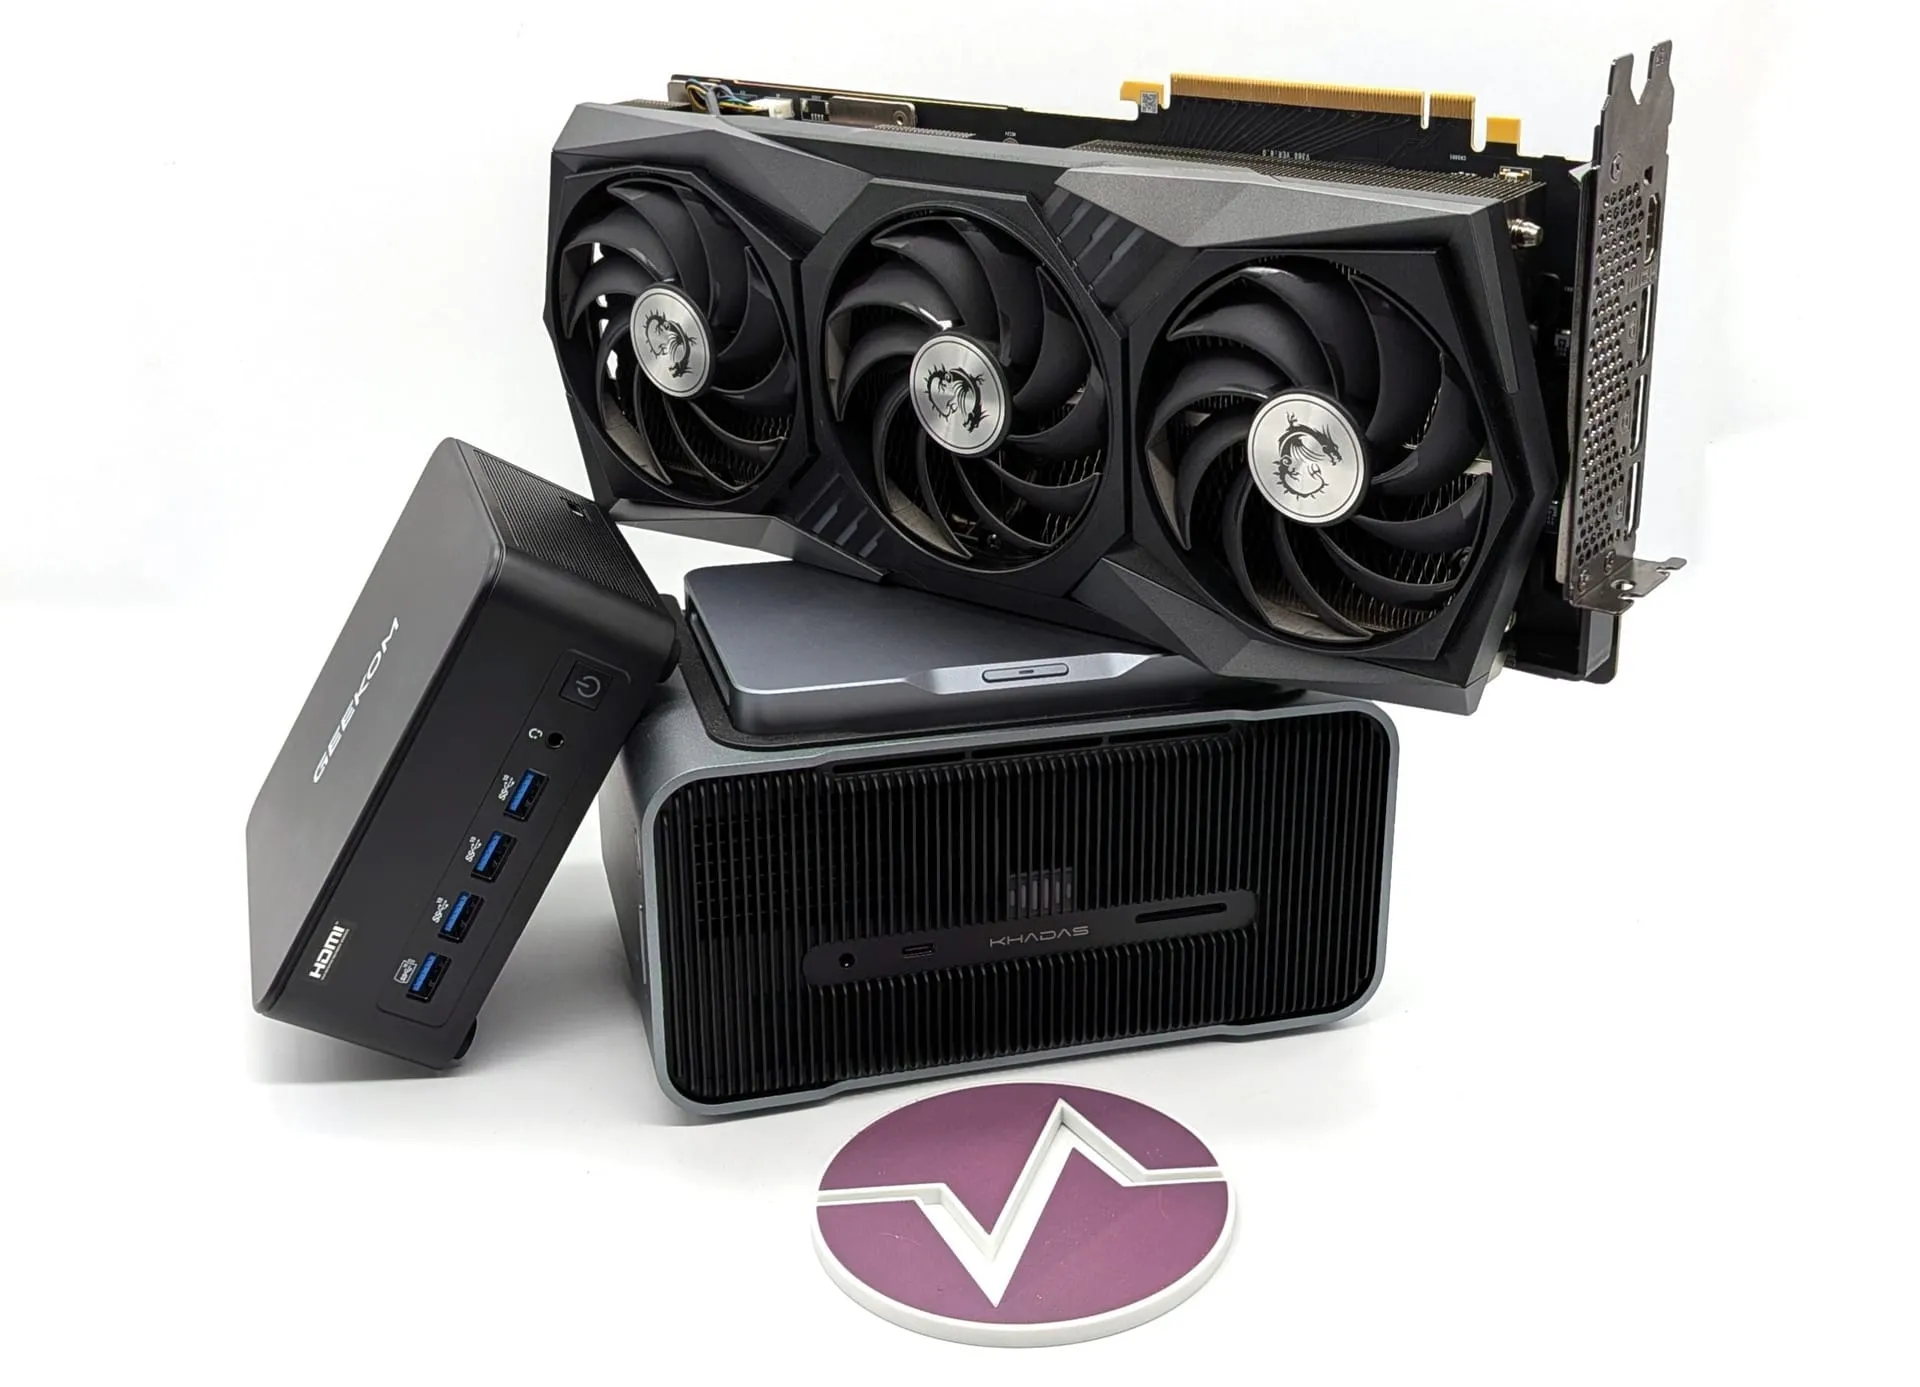
The quest to understand the true power of local Artificial Intelligence often boils down to a critical hardware question: does the graphics card matter? A recent comparison of local language models across three distinct computing setups revealed fascinating, and sometimes frustrating, differences in performance.
The test pitted three different local AI systems against each other, each running on a distinct graphical architecture. These systems were benchmarked across environments utilizing integrated graphics (iGPU), an external graphics card (eGPU), and a dedicated graphics card (dGPU). The results demonstrated that the quality of the hardware fundamentally shapes the AI experience.
The performance gap was stark. The system utilizing the integrated graphics (iGPU) repeatedly struggled when tasked with complex operations, often failing to handle demanding computations. In contrast, the system running on a dedicated graphics card (dGPU) proved significantly more reliable. It successfully solved several complex tasks and even managed advanced operations, such as successfully implementing peer-to-peer file transfer after requiring a minor correction.
While the dGPU system showed superior stability, the findings highlight a crucial caveat: there is no single, universally applicable ranking for local AI systems. Success in these tests was not solely dependent on the hardware; the outcome was also heavily influenced by several variables.
The performance also shifted depending on the specific language model being tested, the precise wording of the task, and the amount of revision required from the AI. This complexity underscores that achieving optimal results requires tuning the software and the environment as much as simply upgrading the hardware.
Ultimately, the experiment suggests that while powerful GPUs provide a massive advantage in tackling complex AI workloads, true local AI mastery is a blend of robust computing power and intelligent fine-tuning. The difference between failure and success lies not just in the silicon, but in the synergy between the model, the prompt, and the processing capability.
Buy on Amazon
Credit
