PS5s run local AI models at 100+ tokens per second
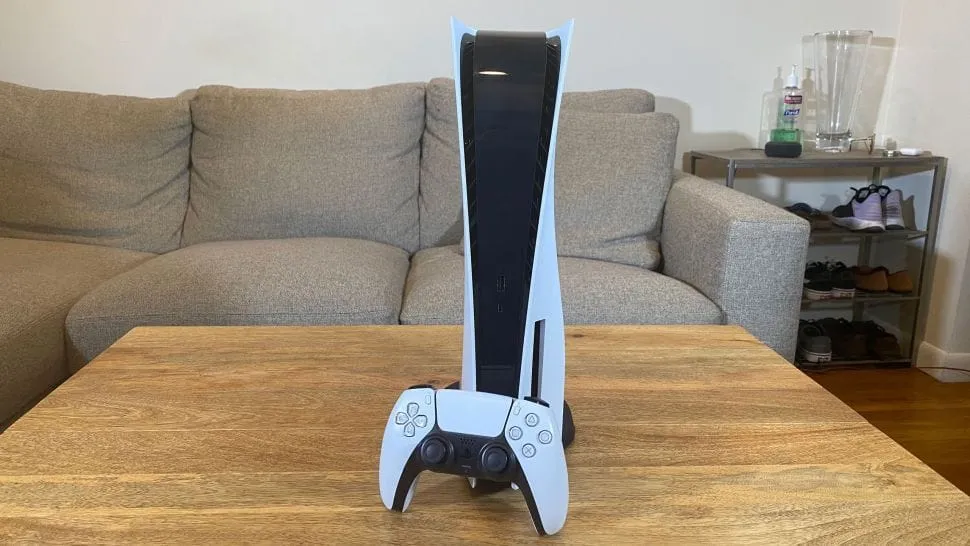
The PlayStation 5, typically celebrated for its blistering gaming performance, is quietly evolving into something far more sophisticated: a local AI powerhouse. For those who have managed to jailbreak the console, the potential for running advanced artificial intelligence models has just become a thrilling reality, pushing the boundaries of what consumer hardware can achieve.
A community of enthusiasts has been quietly hacking the limits of the PS5’s capabilities, turning the console into a unique platform for running Large Language Models (LLMs) locally and offline. This revolution is being driven by clever modifications to existing software, allowing users to leverage the console’s powerful GPU in ways never before imagined.
At the heart of this innovation is a port of llama.cpp, a highly efficient framework designed to run LLMs on consumer hardware. While early attempts focused on CPU-heavy tasks, a significant breakthrough came from customizing this software to natively utilize the PS5’s GPU. This was made possible by tapping into the PS5 Vulkan technology, a port of the RADV graphics driver that unlocks instructions to the GPU, effectively bypassing the console’s traditional limitations.
By opening up GPU access, developers were able to unlock massive potential. Instead of being constrained by the CPU bottleneck, the LLMs could now utilize the dedicated graphics processing unit, dramatically increasing speed and efficiency. This shift solved a long-standing problem: running massive AI models often resulted in system freezes or crashes.
The results have been impressive. One notable achievement involves running a substantial 27-billion parameter model, such as Qwen 27B, directly on the PS5 GPU. This setup managed to deliver outputs at a rate of approximately 20 tokens per second, demonstrating the practical viability of running high-end AI locally on console hardware.
Beyond the behemoths, smaller yet highly capable models are also thriving. Developers have successfully run models like Gemma 4 E4B and Llama 3.2 3B, achieving token generation speeds of 61 and 124 tokens per second, respectively. This performance, combined with the native GPU operation, allowed the system to handle memory demands much more gracefully, allowing for RAM utilization up to 11.4 GiB.
To make this powerful setup user-friendly, the developers also integrated a dashboard. This system provides real-time data on generation speeds, GPU and CPU usage, power draw, temperatures, and how memory is partitioned between the model and the necessary cache. Furthermore, integrating the LLM with llama.cpp’s web user interface means users can chat with these local AI assistants directly from other devices using a standard web browser.
While the console’s GPU and RAM may not compete with the demands of massive AI data centers, this project stands as a testament to the power of open-source innovation. It proves that even on consumer-grade hardware, with the right technical ingenuity, we can harness the power of large language models, turning a gaming console into a surprisingly capable, high-speed AI assistant.
Buy on Amazon
Credit
