Nvidia PAIR clusters GPUs for agentic AI tasks
In the rapidly evolving world of artificial intelligence, where token costs are becoming a major concern, hardware efficiency is the new gold standard. Enter the distributed computing revolution, and at the forefront of maximizing unused processing power is a smart new tool designed to turn idle GPU cycles into tangible savings: the Personal AI Router, or PAIR.
Nvidia is ushering in a new era for local AI execution by introducing PAIR, a local distributed AI clustering tool designed to liberate the spare computational power sitting dormant in your home network. The core idea is simple: if you have a family or shared household with PCs equipped with idle GPU cycles, PAIR allows you to harness those resources to run complex AI tasks privately and efficiently, significantly reducing reliance on expensive cloud tokens.
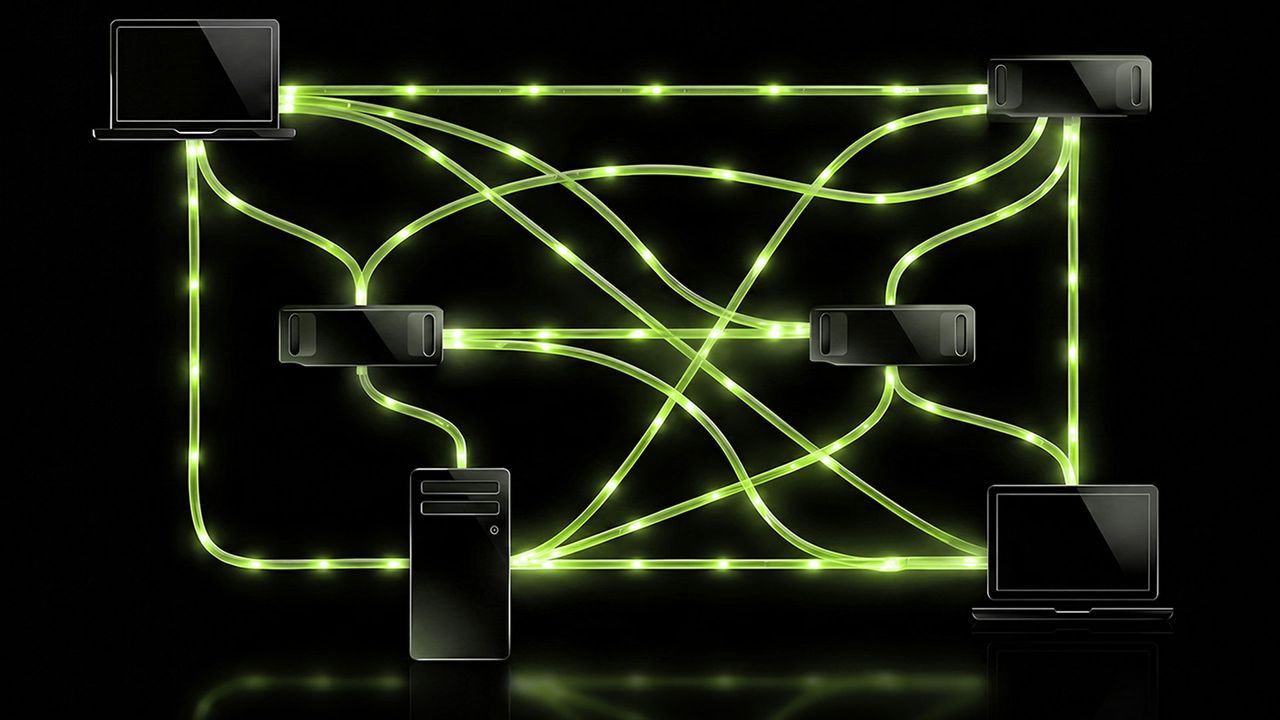
The problem PAIR addresses lies in the current execution model. When a user initiates a large, agentic AI goal on a single machine, the computational contention between the various sub-tasks can cause the entire process to slow down. Imagine a large project that could be broken down into several concurrent steps; running them all on one GPU means they compete for resources, leading to bottlenecks. PAIR solves this by intelligently dispatching these sub-tasks to other systems on your local network that have available GPU capacity.
PAIR acts as a master orchestrator, taking a large goal and distributing the necessary AI sub-tasks across participating nodes. If multiple systems have spare resources, PAIR assigns these tasks to them, allowing the larger agentic work to complete much faster than it would on a single constrained node. Crucially, PAIR is designed to be elastic; it doesn’t reserve dedicated capacity from other PCs; it gracefully utilizes whatever spare cycles are available at any given moment.
Setting up this powerful distributed system is surprisingly straightforward. PAIR functions by creating a proxy layer for popular AI front-ends like LM Studio and Ollama. It manages the flow of work across the network, using methods like mDNS or IP address fallbacks for discovering compatible systems. Participating nodes simply need to be running their preferred AI frameworks and the PAIR installation to join the cluster.
Furthermore, PAIR makes the process flexible regarding model management. Nodes do not need to have identical model sets to participate. If a specific model is available on multiple machines in the network, PAIR broadens the pool of potential processing nodes that can handle a request, ensuring maximum resource utilization.
The hardware support for PAIR is extensive and cutting-edge. The system is compatible with various high-performance graphics cards, including GeForce RTX 20-series and newer cards, as well as systems running Macs with M4-series processors or newer for inference. This versatility extends to powerful hardware like DGX Spark and other GB10 boxes.
Whether you are a dedicated AI enthusiast looking to maximize hardware potential or a user seeking a more private, cost-effective way to run large models, PAIR positions itself as a game-changer. It turns the latent power of your home setup into an active, collaborative AI engine, making distributed, private, and highly efficient AI a reality for everyone.
Credit