Arm AGI CPU: Two 70-core chiplets with 2TB/s UCIe fabric
When Arm first unveiled its vision for an Application-Specific Integrated Circuit (AGI) data center CPU, the focus was on the future. While initial announcements provided a roadmap, the real deep dive into the architecture and design philosophy came later, filling in the technical gaps with precision. The full picture emerged at Hot Chips 2026, where Arm demonstrated that the AGI processor was not just a conceptual leap, but a meticulously engineered piece of hardware poised for commercial reality.
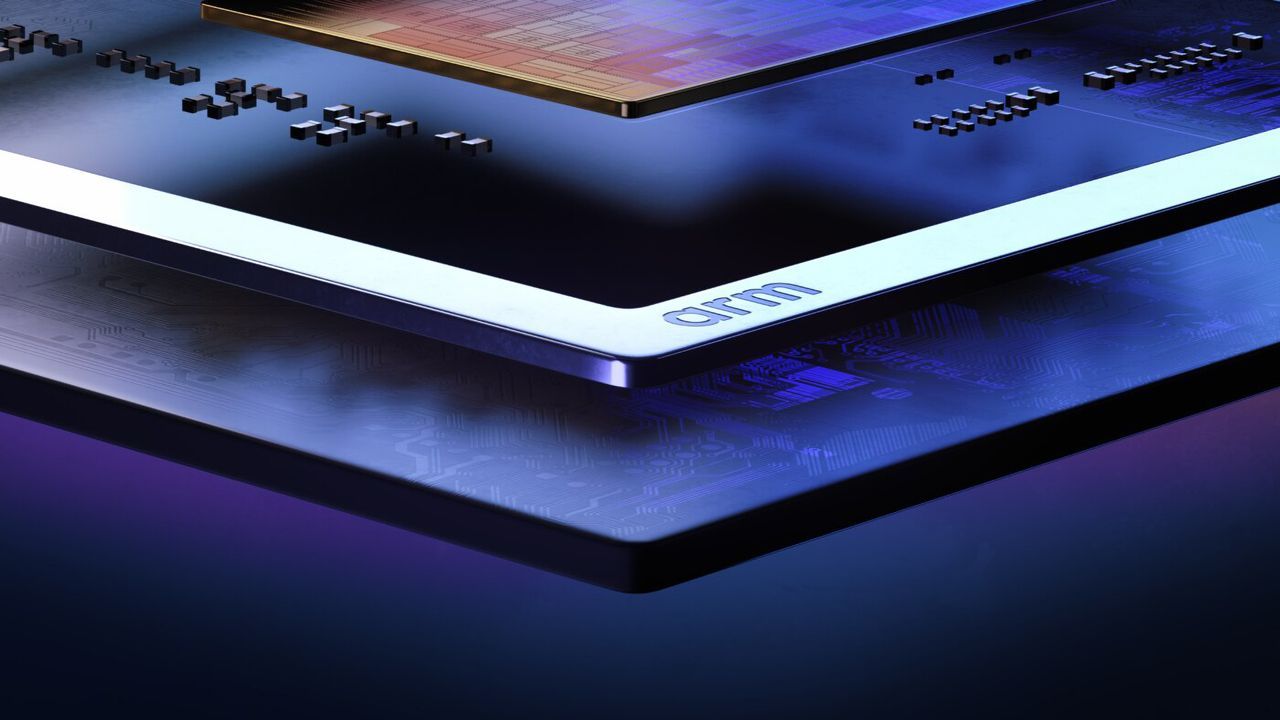
At the core of this new design is a dual-chiplet architecture, leveraging Arm’s Neoverse V3 technology. These chiplets can pack between 64, 128, or 136 cores, designed to handle massive workloads. The hardware is equipped with substantial resources, including advanced vector engines, large caches, and a highly sophisticated memory subsystem. Each chiplet is built on TSMC’s N3P technology, integrating both compute and I/O functions onto a single die, a choice that sets it apart from traditional CPU designs.
What makes the AGI design truly interesting is Arm‘s departure from the mainstream trend of heterogeneous multi-chiplet designs favored by competitors like AMD, Intel, and Nvidia. Instead of separating compute and I/O chiplets, Arm opted for a configuration that prioritizes memory locality and bandwidth. This fundamental decision allows the processor to minimize latency, enabling memory traffic to travel directly between chiplets without needing to traverse a separate memory controller, which promises significant performance gains for latency-sensitive AI workloads.
To manage this complexity, Arm implemented a low-latency interconnect system, the CMN-S3 mesh, which connects cores, memory, and accelerators. This system is further enhanced by a distributed cache and the Super Home Node (HN-S), logic designed to act as a traffic and data distribution center, ensuring communication across the system is swift and efficient.
The memory subsystem is equally remarkable. Arm’s AGI supports coherent NUMA architecture with dual six-channel DDR5 subsystems within each chiplet, theoretically providing up to 845 GB/s of bandwidth. To maximize this speed, the DDR5 controllers are loaded with advanced features, including command scheduling, bank-parallelism optimization, and anti-starvation mechanisms. Furthermore, the system incorporates extensive reliability features, such as Chipkill-class protection, memory scrubbing, and row-hammer mitigation, ensuring stability even under extreme load.
Arm’s approach to managing this vast data flow is highly sophisticated. It employs Memory Partitioning and Monitoring (MPAM) alongside Quality of Service (QoS) prioritization, allowing the system to dynamically manage contention when multiple components compete for DRAM bandwidth. This focus on intelligent resource management ensures that the memory subsystem extracts maximum effective bandwidth for AI processing.
While the architecture is visionary, the focus remains on the final performance metrics. Arm has made claims regarding performance per rack, suggesting a significant boost over existing x86 platforms. Although conventional benchmarks are still pending, the design evidence points toward a processor built from the ground up to optimize the unique demands of agentic AI systems, demonstrating a commitment to pushing the boundaries of server performance through architectural ingenuity.
Buy on Amazon
Credit