Jalapeño AI ASIC beats Blackwell efficiency
Beyond the Chip: How OpenAI Built an AI Accelerator That Rewrites the Rules
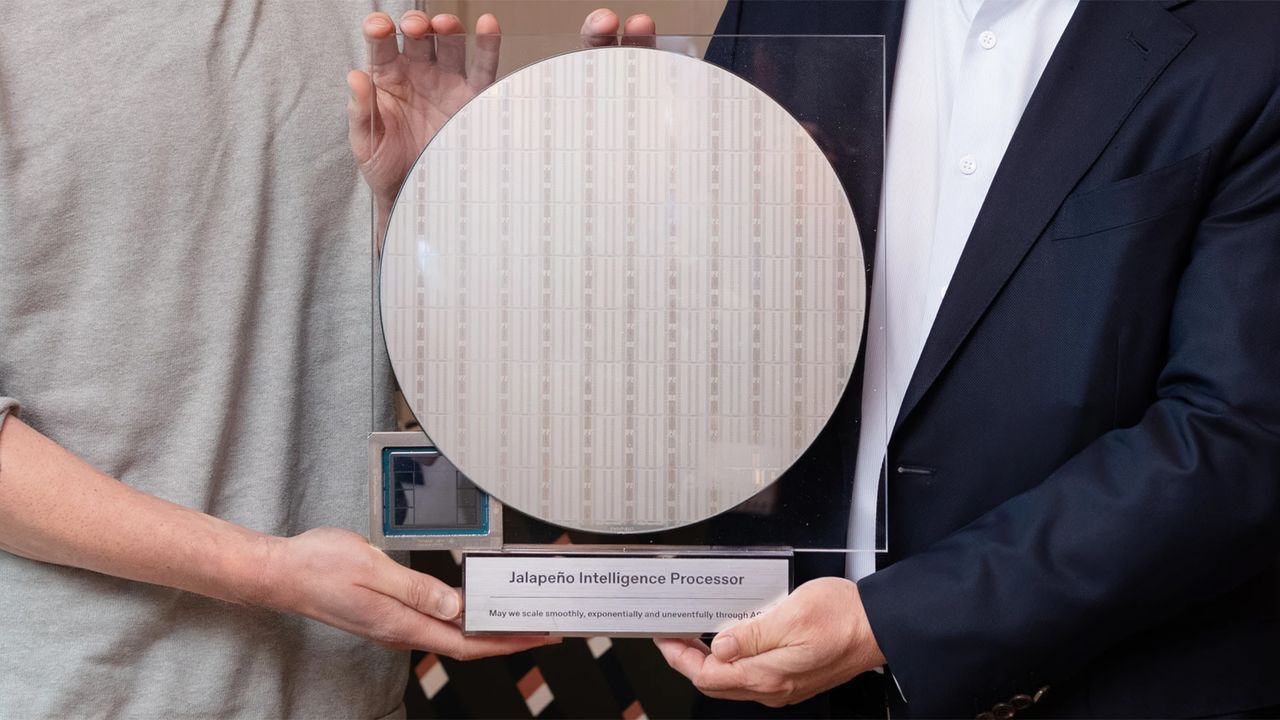
In the fiercely competitive world of artificial intelligence hardware, a new contender has emerged, not just with a new chip, but with a radically different philosophy on how intelligence should be processed. OpenAI has done just that, unveiling the Jalapeño AI accelerator—a custom-built device co-developed with Broadcom that showcases a paradigm shift in AI inference. What makes this processor truly compelling is not just its raw power, but the novel architecture and development process that allowed the team to achieve tape-out in a remarkable nine months.
The Jalapeño is built around a unique NUMA-style spatial architecture, dividing the processing power into 64 core slices, each paired with its own dedicated memory slice. This design is fundamentally different from traditional unified memory systems, allowing frequent data operands to reside close to the compute resources they need, minimizing latency and eliminating the bottlenecks associated with moving data across a shared system. This careful spatial organization, managed by specialized, high-bandwidth collective networks, ensures that data movement is as fast and predictable as possible, allowing the system to manage colossal amounts of information with unprecedented efficiency.
This innovative approach is crucial for handling the complex demands of large language model inference. Instead of forcing all data through a single pathway, Jalapeño employs two distinct communication fabrics: an ultra-fast collective network optimized for tightly coupled inter-core communication, and a separate, more general network-on-chip (NoC) for less critical global access. This separation means the system can prioritize speed and predictability for core operations, yielding a platform built for real-time intelligence.
Beyond the architecture, the Jalapeño demonstrates staggering scale. The system boasts 216 GB of HBM4 memory and up to 32 PB/s of aggregate memory bandwidth. When scaled up to a massive pod configuration, the system can deliver 27 EFLOPS of MXFP4 compute performance, demonstrating the potential for truly massive AI calculations.
But the true revolution lies in the efficiency gains. While competitors focus on sheer peak performance, OpenAI measured its results using the SemiAnalysis InferenceX benchmark, comparing Jalapeño against Nvidia’s GB200 and GB300 accelerators across latency and throughput curves. The results highlighted a significant advantage in performance-per-watt and latency. Jalapeño delivered roughly 1.5X to 1.9X higher peak performance-per-watt and 1.7X to 3.6X lower end-to-end latency compared to the Nvidia systems.
This efficiency advantage suggests that the custom design successfully sidestepped the power penalties often associated with highly generalized hardware. By optimizing data flow at the chip level, the Jalapeño platform proves that achieving state-of-the-art AI performance doesn’t require simply adding more transistors; it requires intelligent architectural design.
The speed of development was equally astonishing. OpenAI credits their rapid timeline—from initial RTL work in February 2025 to tape-out in November—to the use of AI to assist in the design process. By leveraging machine learning to optimize power, performance, and area (PPA), engineers were able to squeeze complex circuitry into highly efficient floorplans, setting a new pace for how custom silicon is developed in the age of LLMs.
Jalapeño is more than just a processor; it is a blueprint for the future of AI hardware, proving that when custom design, intelligent data movement, and efficiency are prioritized, the next generation of computing can deliver performance that truly matches the demands of artificial intelligence.
Credit
