Jalapeño ASIC outpaces Nvidia GPU by 1.9x throughput and lower latency
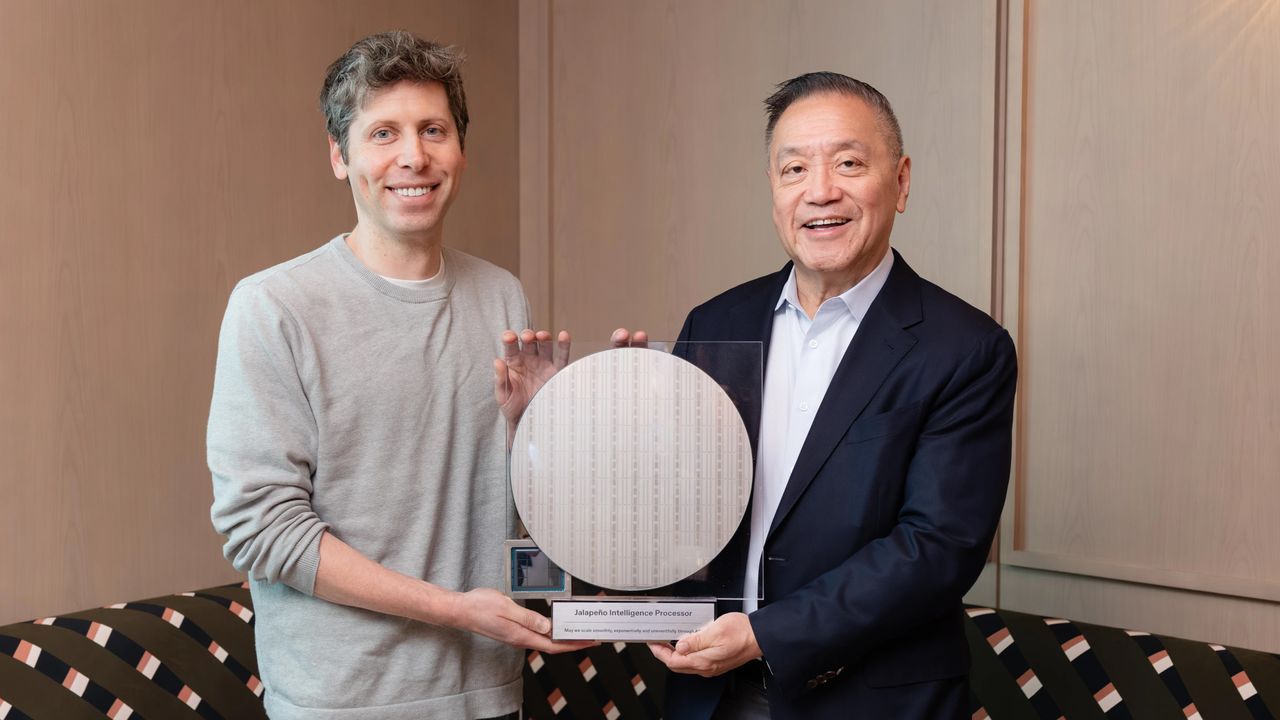
The race for the next generation of artificial intelligence hardware just got a serious shake-up. In a move that signals a major shift in the AI compute landscape, OpenAI has unveiled its proprietary chip, Jalapeno, which is challenging the long-held dominance of Nvidia with impressive efficiency gains.
This isn’t just incremental progress; it’s a fundamental rethinking of how massive language models run. Jalapeno, a custom-built inference ASIC co-developed with Broadcom, demonstrates superior performance metrics compared to Nvidia‘s flagship GB300 and GB200 systems. The results show that Jalapeno delivers 1.5 to 1.9 times more throughput per kilowatt and significantly lower end-to-end latency than Nvidia’s offerings.
The efficiency gap is particularly striking when considering the power demands. The Jalapeno chip operates with a 700W power draw, directly contrasting with the 1,200W to 1,400W requirements of competing Nvidia accelerators. This efficiency advantage is most pronounced at low-latency operating points, where the custom chip reportedly achieved staggering gains, offering between 8.6 and 104.3 times more throughput per kilowatt.
The testing benchmarked Jalapeno against some of the largest and most demanding open models, including GPT-OSS 120B, DeepSeek R1 670B, and Moonshot AI’s 1-trillion-parameter Kimi K2.5. OpenAI highlighted that the performance advantage was widest in low-latency settings, proving that highly optimized custom architecture can deliver peak performance without unnecessary power waste.
Beyond raw speed, the architecture also cleverly addresses one of the semiconductor industry’s most pervasive bottlenecks: High Bandwidth Memory (HBM). Each Jalapeno package features 216 GiB of HBM4, packing significantly more memory per watt than comparable Nvidia systems. This design directly targets the exposure of aggregate HBM bandwidth, rather than simply adding more memory capacity.
The broader context for this development is defined by a severe semiconductor crunch. The global shortage of HBM capacity is acute, with memory suppliers struggling to keep pace with demand. This scarcity has led to intense focus on optimizing chip design, as evidenced by Nvidia‘s reported testing of lower-memory configurations on its Rubin Ultra designs. Meanwhile, industry experts note that HBM now consumes roughly three times the wafer area of DDR5 for equivalent capacity, creating a widening gap between memory and compute technology.
As the industry moves forward, the momentum is building. While Jalapeno is slated for deployment in OpenAI’s data centers later this year, the development is far from over. A second-generation chip is nearing tapeout, and concept work for a third generation is already underway, ensuring that this innovative approach to AI acceleration will continue to redefine the technological frontier.
Credit
